Finding potential bugs is only the beginning
Microsoft FORGE Lab used an analysis tool codenamed MDASH to search for potential security flaws in selected Linux kernel subsystems. Detection was only the start: each result had to be turned into a reproducible issue that would be useful to the people maintaining the code.
According to Microsoft, the initial scans produced 26,502 detections in about two weeks. The work has so far resulted in 59 public reports submitted to the Linux project. These figures do not represent a comparison between distinct vulnerabilities: multiple detections could share a root cause, relate to issues already reported, or lack sufficient security impact to warrant a separate report.
The research illustrates an important distinction between expanding a search and producing results that can feed into maintenance work. AI contributed to code review and reproduction attempts, but turning the findings into reproducible bugs, reports and patches required months of expert investigation and collaboration with Linux maintainers.
An alert’s value, then, lies not just in flagging a potential anomaly, but also in the ability to verify it and communicate it with information useful for review.
What the team did and what it found
Microsoft’s FORGE Lab used a tool called MDASH to analyze a subset of Linux kernel subsystems. According to the team’s published results, one full-time researcher and one intern led the work over three months. The scans took place between late May and mid-June 2026.
The selection focused on security-sensitive components, including networking subsystems, file systems and security modules. The team chose components with no obvious dependency on specialized hardware, a criterion it said made a unified validation process easier.
By the time the results were published, the work had led to 59 public reports submitted to the Linux project and 33 assigned CVE identifiers. Fixes corresponding to 38 of the reports had also been merged into the kernel’s mainline branch. These are distinct outcomes: reports communicate the issues, CVEs identify them, and merged fixes indicate that changes have been integrated into the main codebase.
The team also confirmed working local privilege-escalation exploits that gained root privileges for eight of those CVEs in controlled laboratory environments. In some cases, the tests required non-default configurations or disabled mitigations. That result does not apply to all the reports.
How the analysis and validation process worked
According to Microsoft, the team selected several Linux kernel subsystems, including networking, file systems and security modules. It prioritized security-sensitive components without an obvious dependency on specialized hardware to make validation in QEMU easier.
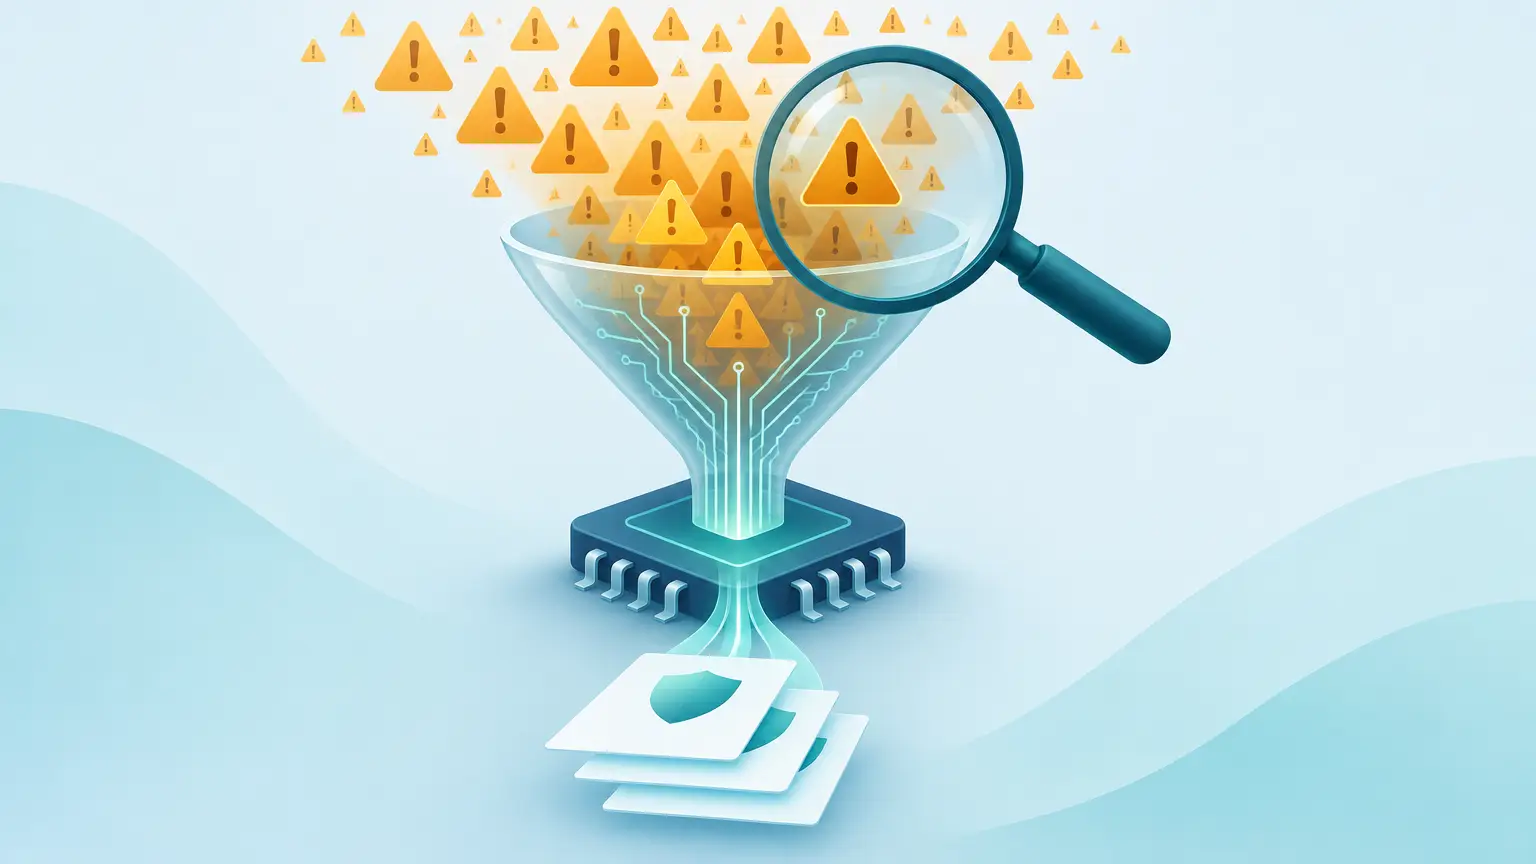
The initial MDASH scans generated 26,502 detections in about two weeks using two servers. The team then filtered out low-confidence claims using MDASH confidence levels and additional rapid-triage agents. This reduced the set to 11,769 candidates.
Next, proof-of-concept generation agents attempted to reproduce the issues in QEMU. Experts reviewed the 621 cases with proof-of-concept evidence. Their work involved identifying root causes, grouping duplicates and preparing reports for submission to the project maintainers.
The process did not end with that review. Agents helped draft fixes, but human validation, subsystem expertise and iterations with maintainers remained essential.
Several models were used at different stages, including Sonnet 4.6 and GPT-5.4 for scanning, and GPT-5.5 and Opus 4.6 for reproduction. Their use at different stages does not, by itself, amount to a comparison of their effectiveness.
What the data does and does not show
The figures describe different stages and should not be interpreted as equivalent counts of vulnerabilities. According to Microsoft, the initial analysis produced 26,502 raw findings. After filtering and reproduction attempts, 621 cases had proof-of-concept evidence. These led to 59 separate public reports: approximately 9.5%.
That proportion does not mean the other cases were false. In 266 cases, or 42.8% of the 621, the root cause matched that of another case, so a single patch could resolve them together. Not submitting a separate report could therefore mean that the issue was already covered by another report, not that the evidence lacked value.
Nexional analysis: the distinction between cases and reports matters when interpreting the result. Counting every case as a separate vulnerability would inflate the total; treating every case without a separate report as false would also distort it.
The available excerpt does not provide a complete breakdown of the reasons behind every decision to discard a case. Nor does it provide enough comparative data to calculate an overall detection rate, establish a cost per vulnerability or conclude that one model is superior to another.
Business application: a code review pilot
Consider a hypothetical case: a company wants to review a security-sensitive component it owns and has a technical team responsible for maintaining it. Rather than extending the analysis to the entire application, it could start with a pilot limited to that component and a specific version of its code.
The team would first define the scope, test environment and criteria for admitting candidates for review. It would then use AI to flag potential flaws and conduct an initial triage of the alerts, for example to separate those lacking sufficient information from those warranting closer investigation. That filter should record discarded cases so specialists can review them if necessary.
Specialists would then attempt to reproduce the cases in an isolated environment, group those sharing a root cause, and document the evidence and possible fixes. The decision to change the code would remain with the responsible team.
To evaluate the pilot, the company could track candidates reviewed, reproducible cases, distinct root causes and human time spent. These metrics would help assess the process in its own context, not promise a success rate. The figures from Microsoft’s Linux kernel study describe that specific work and are not a forecast of the company’s results.
Conclusion: automate the search, retain human judgment
According to Microsoft, the work combined detection of potential bugs at scale with proofs of concept, expert review and collaboration with maintainers. The process did not end with generating alerts: it also included preparing reports and reviewing fixes.
Nexional analysis: the value of a security assistant should not be measured solely by the volume of alerts it produces. What also matters is how much it helps turn them into well-founded decisions and verifiable fixes. To assess that contribution, it is useful to follow each finding through the entire process: what evidence supports it, who reviews it, how its priority is determined and what happens after a solution is proposed.
From this editorial perspective, automation does not mean delegation without oversight. A code review process should assign human responsibility, retain reproducible evidence and establish metrics that track both progress and discarded cases. This allows the team to assess the tool’s usefulness without confusing activity with results.
In our view, automation is most useful when it expands people’s capacity to make decisions rather than promising complete autonomy. Review your security process with that principle in mind.